System Architecture
NilePlateID uses a modular architecture with three main pipelines.
Overview
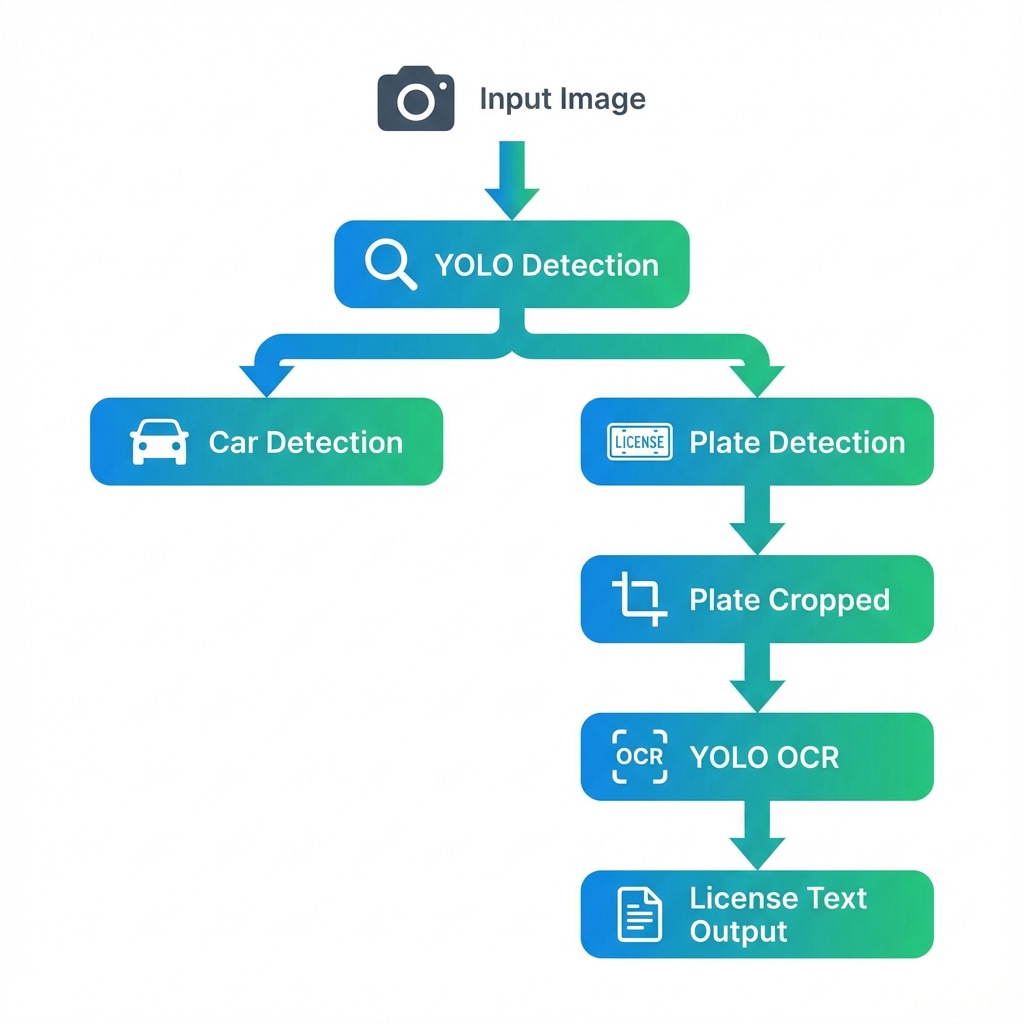
Input Image/Video
    │
    ├─── Classical CV Pipeline ───► Morphological Detection ───► EasyOCR
    │
    ├─── YOLO Pipeline ───► YOLOv11 Detection ───► YOLO OCR ───► Arabic Text
    │
    └─── ReID Pipeline ───► Car Detection ───► Feature Extraction ───► Gallery Matching
Components
1. Detection Module (src/pipeline/)
| File | Purpose |
|---|---|
detection.py |
YOLO wrapper for car/plate detection |
ocr.py |
EasyOCR backend |
yolo_ocr.py |
Custom YOLO OCR for Arabic |
enhancement.py |
Image preprocessing |
association.py |
Plate-to-car matching |
visualize.py |
Debug visualization |
2. ReID Module (src/reid/)
| File | Purpose |
|---|---|
search.py |
Gallery embeddings & matching |
visualize.py |
ReID debug visualization |
3. Streamlit App (src/app_pages/)
| Page | Function |
|---|---|
classical_page.py |
Traditional CV + EasyOCR |
pipeline_page.py |
YOLO detection + OCR |
training_page.py |
Model training dashboard |
reid_page.py |
Vehicle re-identification |
future_work_page.py |
Roadmap & limitations |
Data Flow
Detection Flow
Image → YOLO Detection → [Car, Plate] boxes
    → Crop plate region
    → YOLO OCR character detection
    → Assemble plate text
    → Store car crop indexed by plate ID
ReID Flow
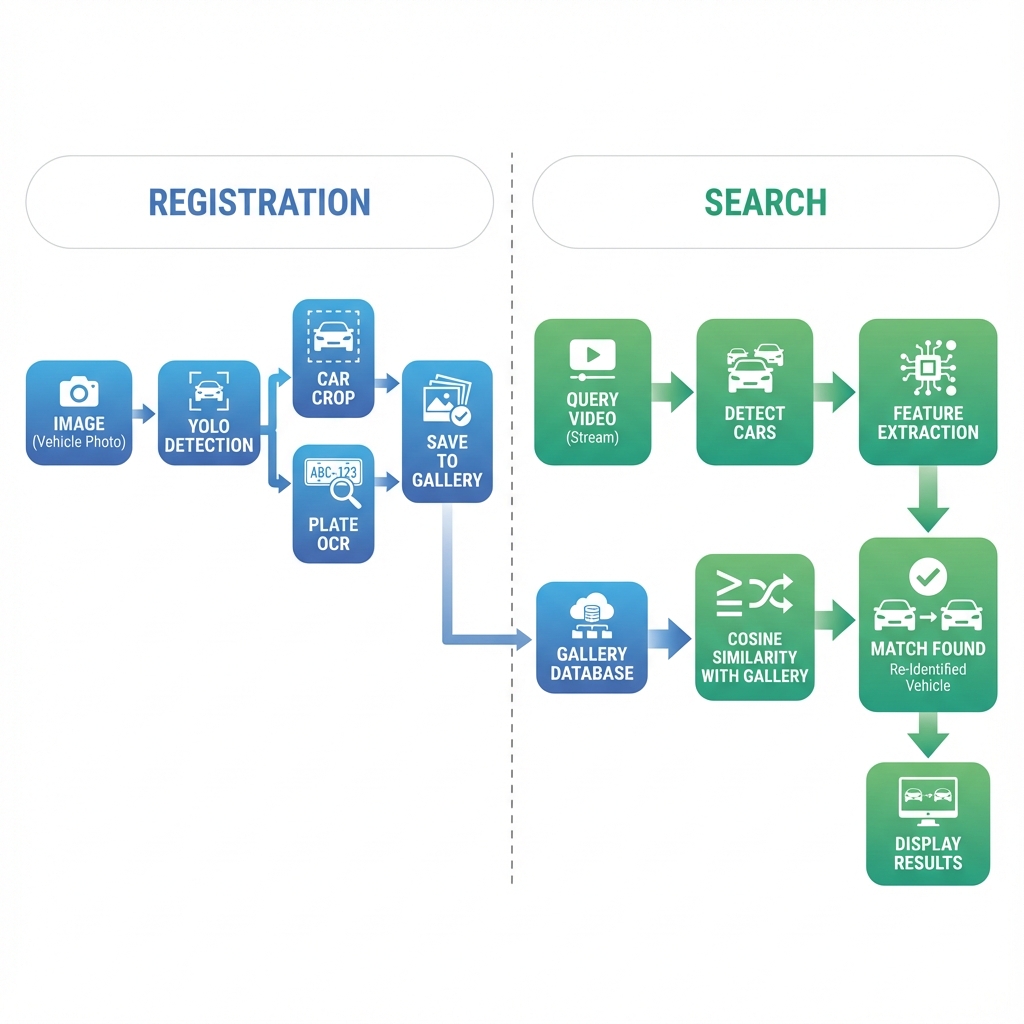
Registration:
    Image → Detect car → OCR plate → Save to gallery/{plate_id}/

Search:
    Query video → Detect cars → Extract features
    → Compare with gallery embeddings
    → Return matches above threshold
Model Architecture
YOLO Detection
- Backbone: CSPDarknet with C3k2 blocks
- Neck: PANet for multi-scale feature aggregation
- Head: Detection heads at 3 scales (P3, P4, P5)
ReID Model
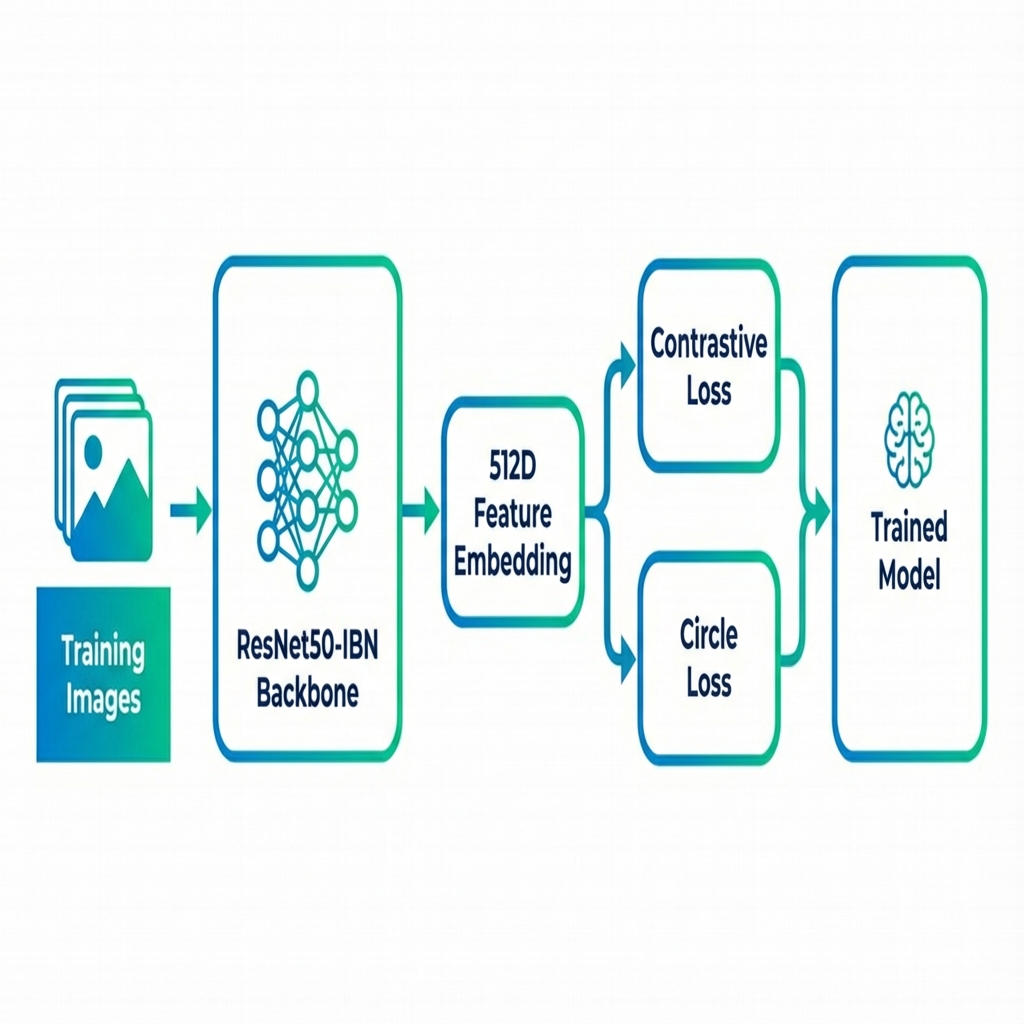
- Backbone: ResNet50-IBN (Instance-Batch Normalization)
- Embedding: 512-dimensional feature vector
- Loss: Contrastive + Circle Loss